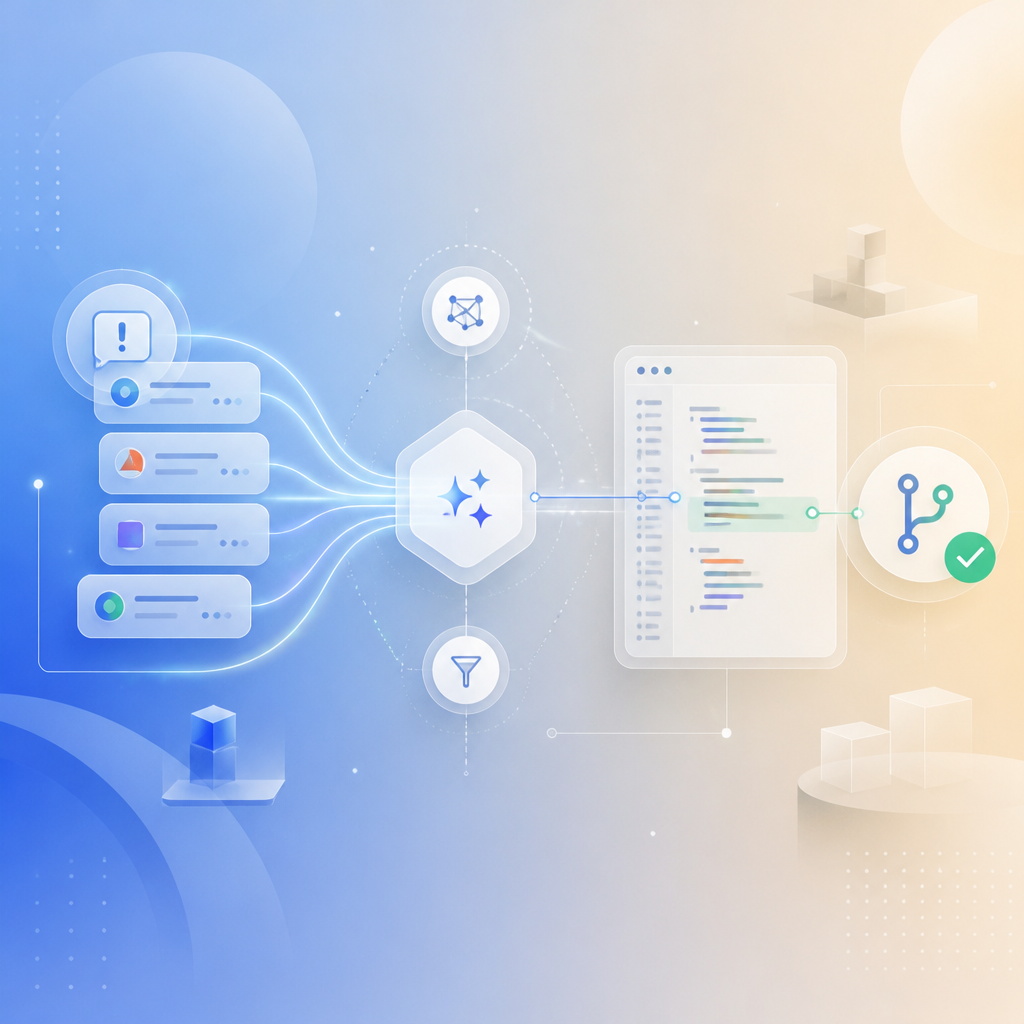
Dev-tool teams drown in GitHub issues because many requests are one of three things: a missing feature, a partly built one, or a documentation gap where the feature already exists. Checking each request against the codebase sorts them quickly. The real gaps can then go to a coding agent and arrive as pull requests your team reviews like any other contribution.
That sorting step is the part most teams skip. It's faster to triage by vibe — label it "feature request," add it to a project board, revisit in six months — than to actually go open the repo and check. But skipping it is why issue trackers at dev-tool companies balloon past a thousand open items while a third of them are already possible with a flag no one documented.
Why do GitHub issues pile up faster for dev-tool companies?
Because the feedback is public and multi-source by default. A SaaS company with a closed user base gets feedback through support tickets and sales calls — channels someone owns. A dev-tool or open-source project gets the same request filed three different ways: a GitHub issue, a Discord thread, and a comment on a docs page, often from three different users who never saw each other's post.
None of those channels talk to each other. The result is duplicate issues with slightly different wording ("can't set custom timeout" vs "timeout config missing" vs "feature request: configurable timeouts"), each with its own comment thread and its own partial reproduction steps. Deduping manually means someone reading every new issue title against every open one — which doesn't scale past a few hundred issues, let alone a few thousand.
The fix isn't a better label taxonomy. It's pulling every source — issues, Discord, docs comments, support if you run any — into one place where duplicates get grouped automatically before a human looks at them. That's a pattern-finding problem, not a tagging problem, and it's the same one covered in The Best Feedback Tools for Dev-Led Teams With No Product Manager for teams without anyone doing this full-time.
How do you classify a feature request against the actual codebase?
Every incoming request falls into one of three buckets once you check it against the repo, not against your memory of the repo:
- Exists. The feature is already shipped, often behind a config flag, an undocumented API parameter, or a plugin. The user filed a bug because they couldn't find it.
- Partly built. There's a half-implemented code path, a feature flag stuck in beta, or an internal API that does 80% of what's asked but was never exposed. These are the cheapest real wins — the scaffolding already exists.
- Missing. Nothing in the codebase does this. It needs real design and real code.
Example: a user asks for "webhook retries with backoff." A quick grep shows a retry_count field already passed into the webhook dispatcher, unused downstream — partly built. A different user asks for "export audit logs to S3." Nothing in the repo touches S3 or any object store — missing. A third asks for "dark mode in the CLI output" and the CLI already respects NO_COLOR and a --theme flag nobody documented — exists.
Each bucket gets a different response, and only one of them — missing — goes anywhere near a coding agent. The other two are the fast closes, and they're the majority. Projects that have bothered to measure it generally find docs gaps and partly-built duplicates account for well over half of open "feature request" issues; the exact split depends on how good your docs are to start with.
Why are docs-gap fixes the fastest wins?
Because the engineering work is already done. If a feature exists but isn't discoverable, the fix is a docs PR, an example snippet, and maybe a one-line mention in the CLI's --help output. That can close in an afternoon and be linked back to the original issue, which also makes the next five people who hit the same gap find the docs page via search instead of filing issue #6.
This is also where "partly built" requests get resolved cheaply if the remaining 20% is small: finish the implementation, write it up, close three duplicates at once. The alternative — scoping it as a brand-new feature because nobody checked what already existed — means paying full build cost for work that was half-finished eighteen months ago by someone who left the team.
What labels and templates actually help?
GitHub issue templates earn their keep when they force the triager to answer the exists/partly-built/missing question up front, not after the fact. A useful template structure:
- A required field: "Have you checked the latest docs/changelog for this?" with a link.
- A reproduction or use-case field, so vague requests get bounced back for detail instead of sitting in the backlog unscoped.
- Labels that encode the classification, not just the topic:
status:exists-undocumented,status:partial,status:missing, alongside your usual area labels.
The point of the labels isn't reporting — it's routing. "Exists-undocumented" goes to whoever owns docs this week. "Missing" and confirmed "partial" requests are what goes into scoping. See Open Source Guides for broader maintainer practices if your triage process needs a rewrite, not just a template update.
How do agent-built PRs fit into this process?
Once a request is confirmed missing (or partial with real scope left), it can be handed to a coding agent — your own build agent or a cloud agent such as Claude Code — to open a pull request against the issue. The agent needs the same context a human contributor would: the issue, the relevant files, any related partly-built code, and constraints on what not to touch. How that handoff and scoping actually works is covered in full in How AI Agents Open Pull Requests (and Where Humans Approve) and Spec-Driven Development — worth reading before you wire this up, since scoping badly is the single most common way agent PRs go sideways.
The PR that comes back should be reviewed exactly like a community contributor's: CI runs, a maintainer reviews the diff, tests are checked, nothing merges without a human approving it. That's true whether a person or an agent wrote it. Security review of AI-generated diffs specifically — dependency changes, permission scope, generated test coverage — is its own checklist, covered in Automating Feature Development: From Signal to Pull Request and a dedicated security piece; don't skip that step just because CI is green.
How do you close the loop on the issue and in Discord?
Closing a GitHub issue with "fixed in PR #412, shipping in v2.3" is the minimum. The miss most teams make is not going back to the five duplicate issues and the Discord thread where the same request surfaced, and not confirming after release that the fix actually resolved what people asked for rather than a narrower interpretation of it. That after-release check — did the request stop recurring, did the workaround threads go quiet — is the step that separates "we closed the ticket" from "we fixed the problem," and it's detailed in Did It Work? How to Measure Whether a Shipped Change Moved the Needle.
This is the full loop VocxAI is built around: VocxAI is the AI agent that keeps improving your product: it finds the patterns in customer feedback from any tool you use, works out what's wrong in your code, has AI agents build the fix for your approval, then checks whether it worked and acts on what it learns. For a public-issue-tracker team, that means it groups the GitHub issue, the Discord thread, and the docs comment as one request, checks the repo to tell you if it's a docs fix or real work, and if it's real work, routes it to an agent that opens a PR you review — then tells you afterward whether closing those issues actually reduced the duplicate filings.
What metrics show whether your triage process is working?
Two numbers matter more than open-issue count:
- Duplicate rate — the share of new issues that are the same request as one already open or recently closed. A falling duplicate rate means your docs and changelog are doing their job, or your labeling is catching repeats before they multiply.
- Reopen rate — the share of closed issues that get reopened or re-filed within a release cycle or two. A rising reopen rate usually means issues are being closed on a technicality (the PR merged) rather than confirmed fixed (the behavior the user actually wanted now works).
Track both over a few release cycles rather than one sprint — duplicate rate in particular lags behind docs fixes by a release or two as search indexes catch up and old issue links get surfaced again.
FAQ
How do open-source projects prioritise feature requests?
Most start by deduplicating across channels (issues, Discord, docs comments), then checking each surviving request against the codebase to see if it's a docs gap, a partly-built feature, or genuinely missing. Only the confirmed gaps get scoped and prioritized against maintainer bandwidth and community demand signals like reactions or linked duplicates.
How do you triage GitHub issues?
Use a template that forces reporters to check existing docs first, group duplicates across all your feedback channels, then classify each unique request as exists, partly built, or missing by checking the repo directly rather than assuming from the title.
How can you tell a feature request from a documentation gap?
Check the codebase for the behavior the user describes. If it's already implemented — a config flag, an undocumented parameter, a plugin — it's a documentation gap, not a feature request, and the fix is a docs PR, not new code.
Can AI agents open pull requests for GitHub issues?
Yes. Once a request is confirmed as a real gap, a coding agent — your own build agent or a cloud agent such as Claude Code — can be given the issue and relevant code context to open a pull request. It still needs human review and approval before merging, the same as any contributor's PR.
Should AI-written PRs be reviewed differently?
The core review — CI, tests, a maintainer reading the diff — should be the same as for any contributor. Teams often add extra scrutiny on dependency changes, permission scope, and test coverage specifically because an agent won't flag its own uncertainty the way a human contributor might in a PR description.
See how VocxAI builds this for you
VocxAI is the AI agent that keeps improving your product: it finds the patterns in customer feedback from any tool you use, works out what's wrong in your code, has AI agents build the fix for your approval, then checks whether it worked and acts on what it learns.
Sign up for free